Software Testing Unleashed – Better Teams. Better Software. Better World.

Software Testing Unleashed - Better Teams. Better Software. Better World.
Podcast Description
In a world where software drives everything, testing is no longer optional — it’s your superpower.
- How much testing is enough?
- When should you automate?
- What makes a great integration test?
- And how do you keep up when AI, ML, and cloud-native complexity are redefining the rules?
Each week, leading minds from across the software universe — testers, developers, architects, and product thinkers — share practical insights, field-tested techniques, and bold ideas to help you ship better software, faster.
Whether you're scaling your QA strategy, building your first test suite, or leading complex enterprise projects: This is your backstage pass to the tools, tactics, and trends that are shaping the future of software testing. 🚀
Are you ready to unleash the next level of quality in your software? Hit play and join the movement.
Podcast Insights
Content Themes
Focuses on software testing methodologies, AI's impact on development, and quality assurance strategies, with episodes diving into topics like effective test design techniques, the evolving role of testers, and integrating AI into testing processes.
Software testing is no longer just a phase—it’s the foundation of modern engineering and your ultimate competitive advantage.
Welcome to Software Testing Unleashed, the weekly podcast for anyone dedicated to building better software, faster. Hosted by Richard Seidl, renowned expert in software development and testing, this show is your backstage pass to the tools, tactics, and trends defining the next era of Quality Engineering.
Whether you are a QA Engineer, SDET, Developer, or Tech Leader, each week we bring you field-tested insights from the brightest minds in the software universe to answer the industry’s toughest questions:
– Smart Automation: When should you automate, and when is it a trap?
– AI & ML in Testing: How do you maintain quality in a world of non-deterministic code?
– The “How Much” Dilemma: How much testing is actually enough for your specific scale?
– Architecture & DevEx: What makes a great integration test and how do you improve developer experience?
From scaling QA strategies in enterprise projects to building your very first test suite, we bridge the gap between complex theory and practical execution. We dive deep into CI/CD, Cloud-native complexity, and the future of manual vs. automated testing.
🚀 Ready to unleash the next level of quality? Hit play, subscribe, and join a global movement of software professionals shipping with confidence.
One model, three use cases and three different definitions of good
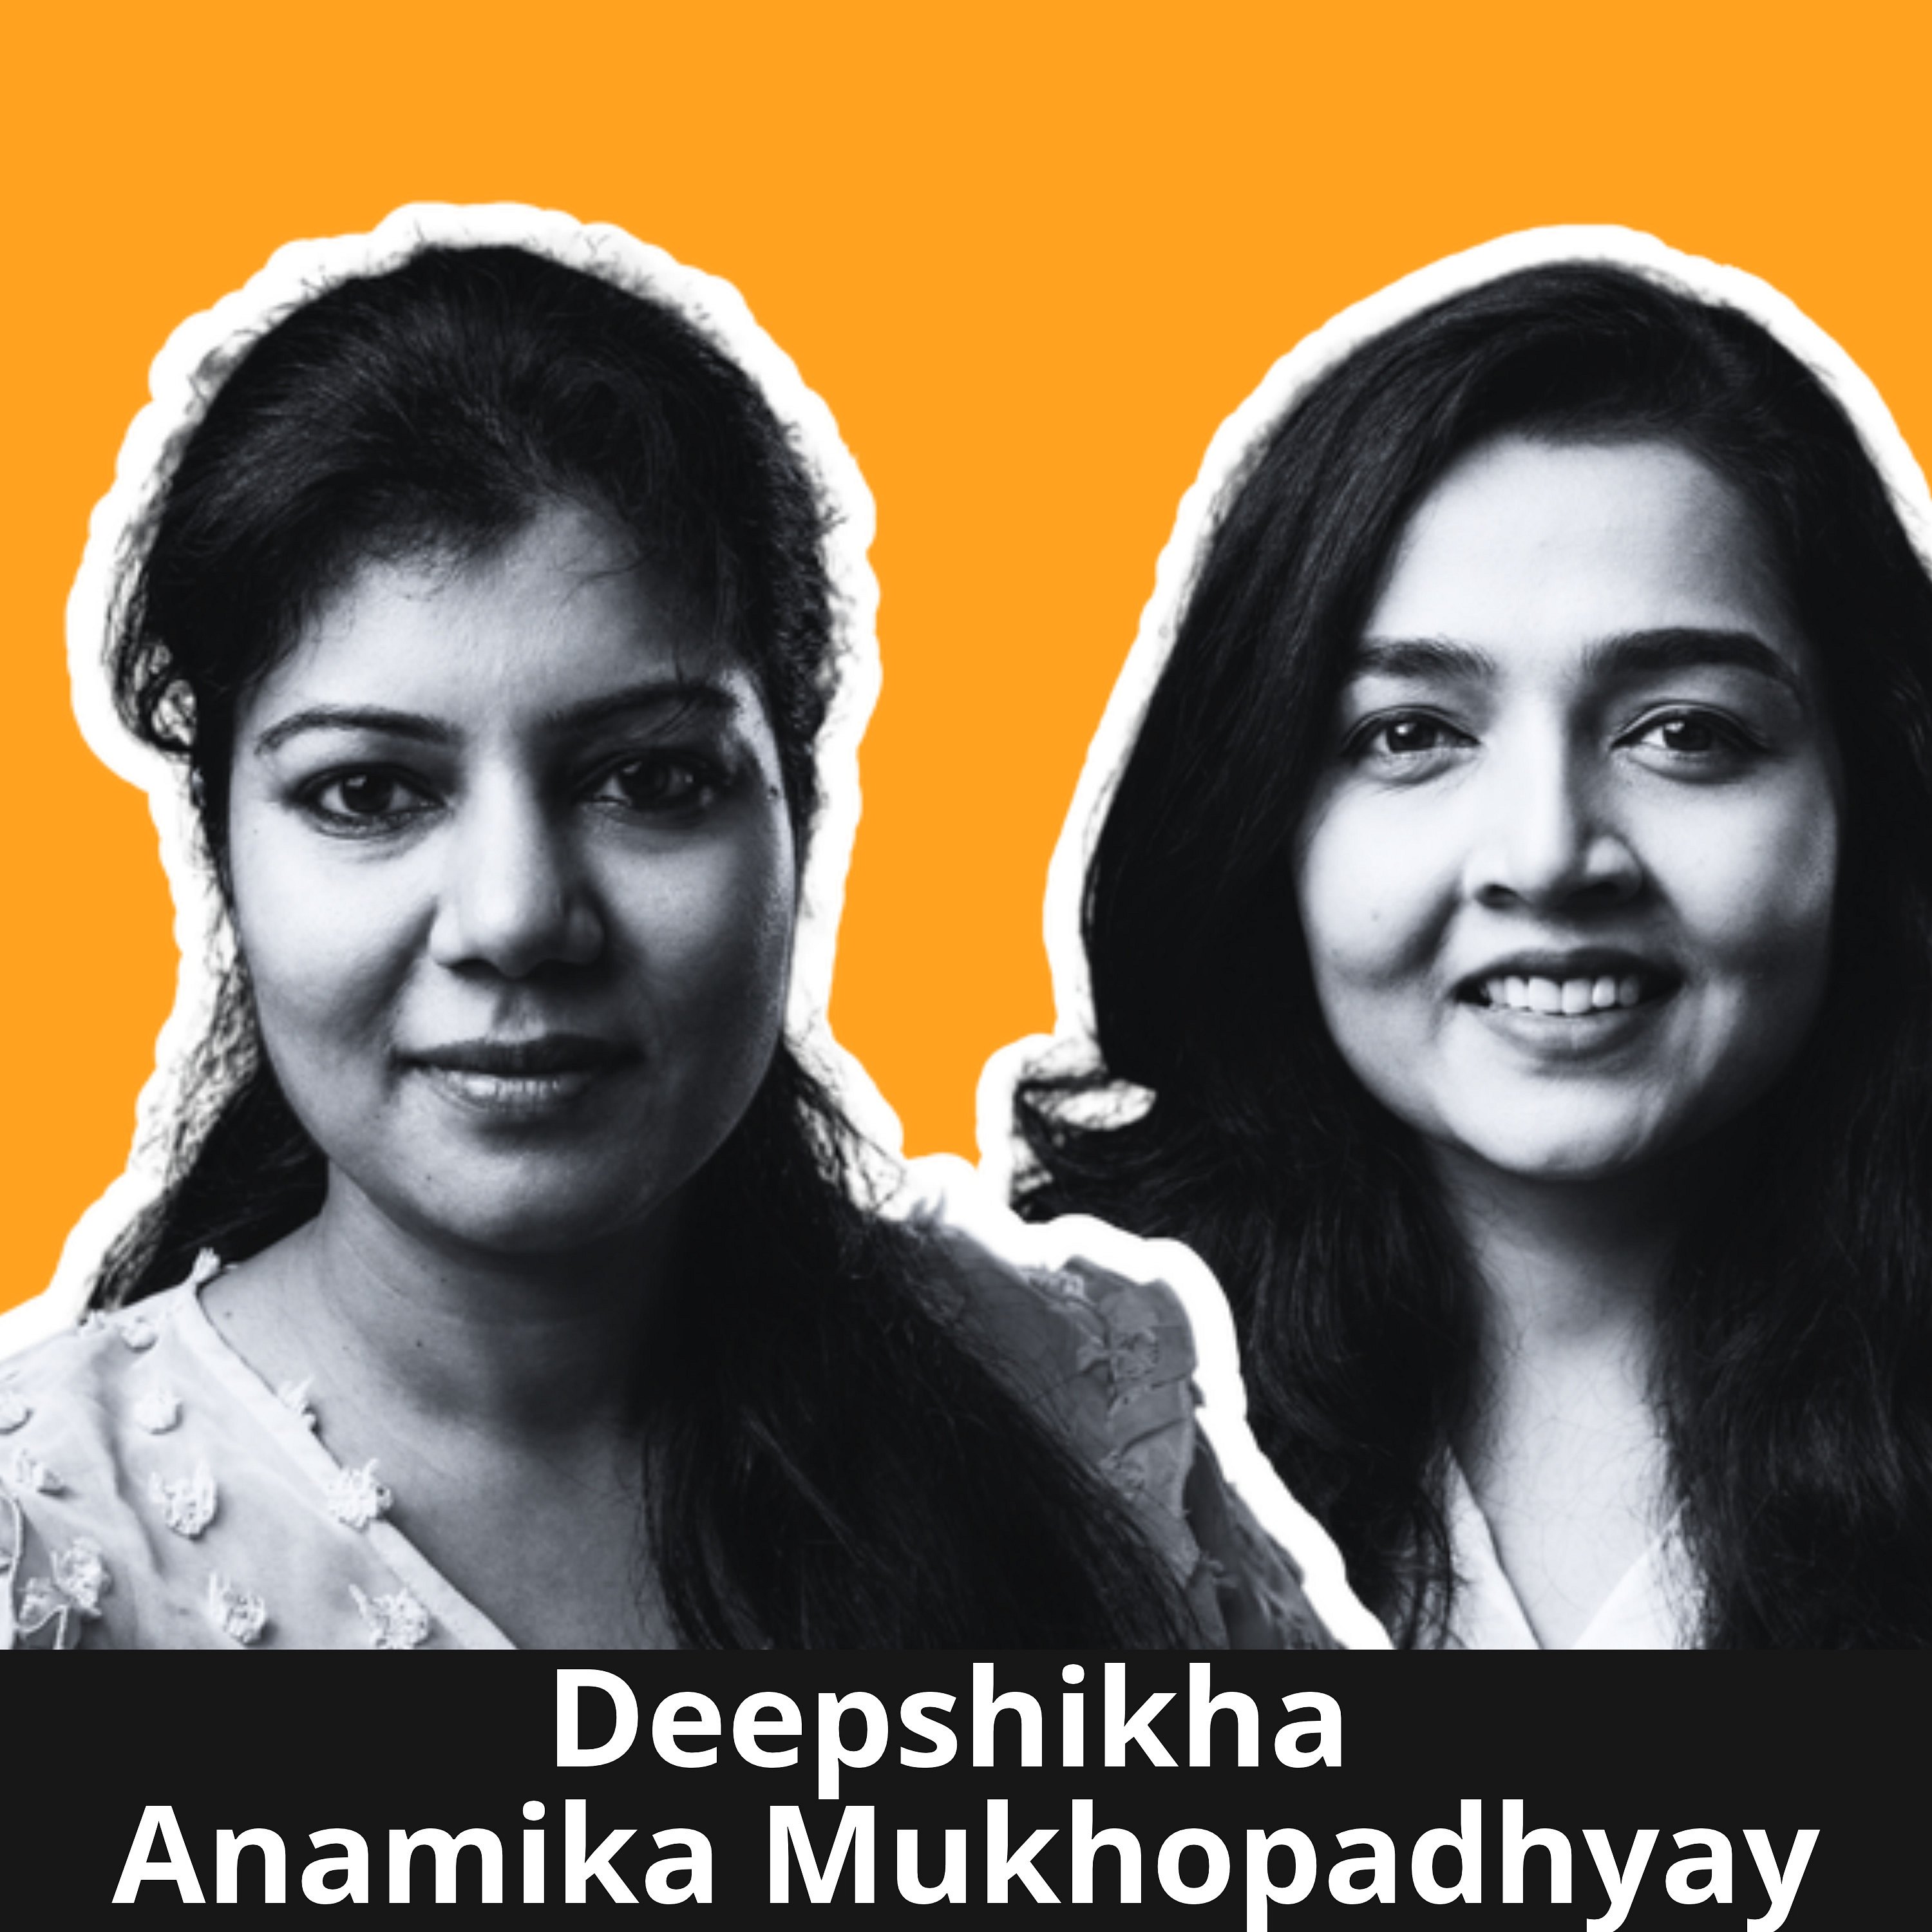
GenAI evaluation turns into a question of better or worse once every answer a model gives could be correct, and that is where Deepshikha and Anamika Mukhopadhyay begin. We talk about why one model needs three different definitions of good as a customer bot, a clinical summarizer and a coding agent, and why most teams they meet in workshops measure whatever their tools give them by default. A faithfulness score like 0.87279 left a room of CXOs asking whether it was a rounding problem; a 12 percent drop in issue resolution and 200 extra tickets did not. And a prepared Reddit post shows how an indirect prompt injection slips past an agent that had blocked every direct one.
”We measure what our tools give us by default.” – Anamika Mukhopadhyay
Deepshikha leads Nagarro’s AI in Testing practice and brings over 13 years of experience at the intersection of software quality and emerging technologies. She specializes in designing AI-driven testing strategies that enhance reliability, accelerate delivery, and help organizations build systems that are not only efficient but also trustworthy and resilient when it matters most.
Anamika Mukhopadhyay is a QA Consultant with over 13 years of experience in software testing and automation and leads Nagarro’s Emerging and Special Tech Practice. Passionate about inclusivity and equal access to technology, she explores AI-driven innovations to advance testing practices. Her focus is on delivering sustainable, accessible, and high-quality solutions that empower diverse users across an evolving digital landscape.
Highlights:
- Anamika Mukhopadhyay hears the same answer in workshops with teams running production AI systems: they measure what their tools report by default, without asking which numbers they need.
- The same model needs different GenAI metrics per use case, from satisfaction and issue resolution for a support bot to groundedness and adoption rate for a clinical summarization tool.
- A dip in the faithfulness score left a CXO room asking about rounding; a 12 percent drop in issue resolution and 200 extra support tickets got their attention.
- GenAI evaluation runs as a loop of offline evaluation on a golden dataset and online evaluation with traces, because a model version can change every two to three weeks.
- Deepshikha's team planted an indirect prompt injection in a Reddit post, and an agent with guardrails against direct injection followed it through its web tool call.
🚀 Do you like the podcast? Then please rate and share it. And feel free to send feedback to [email protected]
Disclaimer
This podcast’s information is provided for general reference and was obtained from publicly accessible sources. The Podcast Collaborative neither produces nor verifies the content, accuracy, or suitability of this podcast. Views and opinions belong solely to the podcast creators and guests.
For a complete disclaimer, please see our Full Disclaimer on the archive page. The Podcast Collaborative bears no responsibility for the podcast’s themes, language, or overall content. Listener discretion is advised. Read our Terms of Use and Privacy Policy for more details.